An HTML site map and an XML sitemap share a name, but their functions are radically different. A site map for visitors organizes human navigation, while an XML file feeds indexing bots. Confusing the two is like trying to solve a usability problem with a tool designed for Googlebot.
XML tags Google ignores: what a sitemap can’t control
Google ignores the <priority> and <changefreq> tags. Adding them to a sitemap.xml file does not change how often pages are crawled or the priority assigned to them. Although documented by Google Search Central, this remains widely misunderstood: most general-audience guides still recommend configuring these tags.
The lastmod tag is reliable only when it reflects an actual content change. Automatically updating this date—for example, with every technical deployment that makes no editorial changes—undermines its credibility with crawlers. If inconsistencies accumulate, Google may eventually ignore it across the entire domain.
An XML sitemap guarantees neither that a URL will be crawled nor that it will be indexed. Google treats it as one signal among many. Internal links remain the primary way to help a page get discovered and recognized as relevant by both bots and visitors.
HTML site map: a navigation structure for visitors
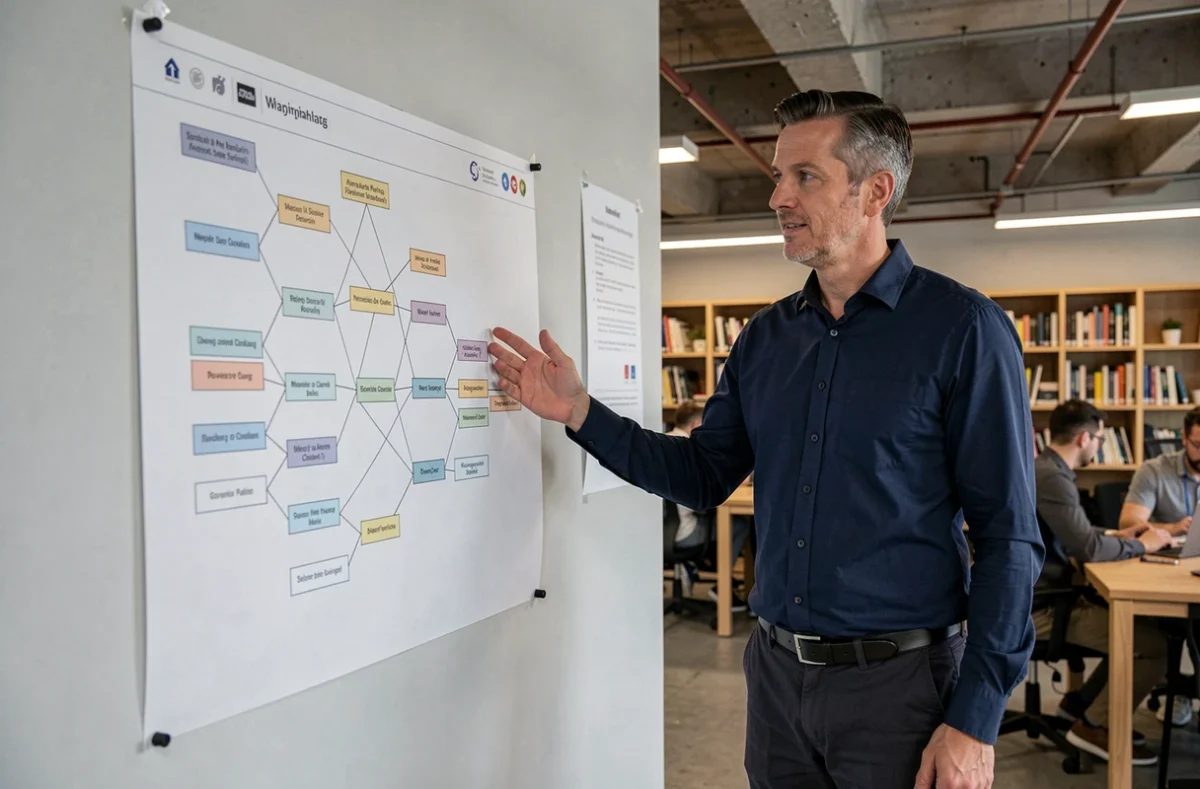
An HTML site map is a static or dynamic document, accessible from the footer, that lists the site’s sections and subsections. Its purpose is strictly user-focused: to provide an overview when the main menu or internal search isn’t enough.
The Francoeur site map illustrates this category-based approach, using clear labels that make it possible to find a page in seconds without relying on the site’s internal search engine.
Completeness alone doesn’t make a site map useful. A raw list of hundreds of links with no hierarchy becomes an obstacle rather than a help. Three principles distinguish a functional site map from a simple dump of URLs:
- Pages are grouped by topic or site section, not by chronological order or technical ID
- Each link label describes the content of its target page (no “Page 1” or raw technical slugs)
- Navigation depth is limited: two hierarchical levels are enough in most cases, with three as the maximum for large editorial sites
Orphan pages and internal linking: the real accessibility problem
A page with no internal links pointing to it is invisible, regardless of whether it appears in the XML sitemap. Orphan pages—those with no internal links pointing to them—are one of the most common blind spots on mid-sized websites.
An HTML site map can act as a safety net for these pages. Adding them to a visible category in the site map creates a navigation path that both visitors and bots can follow. An XML sitemap alone won’t solve this problem because it has no effect on user navigation.
Find orphan pages without paid tools
The most direct method is to compare the list of indexed URLs (using a site: search on Google) with the URLs that are actually linked from at least one other page on the site. Any discrepancy points to a potentially orphaned page.
We recommend cross-checking this with the HTML site map: if a page isn’t listed there and no other page links to it, it is effectively inaccessible to visitors browsing without a search engine.
Structure a site map to suit the size of your project
A brochure website with a few dozen pages doesn’t face the same constraints as an editorial site that publishes daily. The site map format should reflect this.
Small websites
A single HTML page with two heading levels is enough. Each section corresponds to a main menu item, and each link points to a real page. No pagination or filters are needed.
Editorial or e-commerce websites
Once a site has several hundred pages, a monolithic site map loses its usefulness. Two approaches work well:
- A separate site map for each section (blog, catalog, corporate pages), each accessible from a central index page
- A dynamic site map with category filters, generated server-side, that limits what’s displayed to the sections selected by the visitor
- A supplementary alphabetical index for sites whose page titles don’t always match their topic categories
An HTML site map reflects the site’s actual structure, not a theoretical hierarchy frozen at launch. Every addition or removal of a section should be reflected in this document to avoid dead links or phantom sections.
Robots.txt and XML sitemap: submission and technical limitations
The robots.txt file can include a Sitemap: directive pointing to the XML file’s URL. This makes it easier for bots to discover the sitemap, but it doesn’t replace direct submission through Google Search Console or Bing Webmaster Tools.
One often-overlooked point: robots.txt Disallow directives take precedence over the sitemap. Listing a URL in the XML sitemap while blocking it in robots.txt sends conflicting signals. The bot follows the block and ignores the URL in the sitemap.
An XML sitemap is a crawling aid, not a substitute for internal linking or an HTML site map. The three components (robots.txt, XML sitemap, HTML site map) serve distinct functions and complement one another without replacing one another.
A well-maintained site map, with clear labels and a consistent hierarchy, remains the most reliable way for visitors to find what they’re looking for without entering a search query. An XML sitemap, by contrast, speaks to machines. Treating the two as the same tool means ignoring half the problem.